eRacks Systems Tech Blog
Open Source Experts Since 1999
The Future of Memory, and What It Means for Upgradeability
For thirty years the answer to “my machine needs more memory” was the same: open the case, push a stick into an empty slot. That answer is splitting three ways, and the split matters more than the speeds.
Three futures
Sealed. High Bandwidth Memory (HBM) is not a module at all. DRAM dies are stacked on top of each other, wired vertically through the silicon, and mounted on an interposer (a thin silicon layer that carries the wiring) millimeters from the processor, inside the same package. The bus is a thousand bits wide instead of 64, the distance is a fraction of an inch instead of several, and the result is the bandwidth that makes an AI accelerator an AI accelerator. NVIDIA’s H100 and Blackwell parts are built this way, and Intel put HBM on a Xeon (the Xeon Max) for the same reason. The trade is absolute: the memory is soldered into the package, so the amount you buy on day one is the amount you own on day one thousand. The industry name for this kind of assembly, several chips from several processes glued into one package, is System in Package (SiP). Your watch is one. So is the processor in the largest AI clusters.
Flat. JEDEC, the standards body behind every DIMM you have ever installed, published the CAMM2 standard (JESD318) in December 2023. A CAMM2 (Compression Attached Memory Module) is a flat card that screws down onto a bed of contacts instead of standing in a slot, which puts the memory closer to the processor and keeps the signal clean at higher speeds. The low-power version, LPCAMM2, is the interesting one: laptop makers used to solder LPDDR memory to the board to get its speed and battery life, and that killed upgrades. LPCAMM2 puts the same memory on a replaceable card. Lenovo’s ThinkPad P1 Gen 7 ships with up to 64GB of LPCAMM2 at LPDDR5X-7500, and it can be changed with a screwdriver. Desktop CAMM2 boards have been shown by the motherboard makers; volume is still small. The catch is that a CAMM2 is one module carrying both memory channels, so an upgrade means replacing it rather than adding a second stick.
Fabric. In servers, memory is leaving the motherboard. Compute Express Link (CXL) runs over the same physical lanes as PCIe and lets a system treat memory the way it treats a drive: something you add in a slot. A CXL memory expander is a card, or a box, of ordinary DDR5 that the processor sees as more RAM. Current AMD EPYC and Intel Xeon platforms support it, controller silicon is shipping, and the standard has kept moving; the CXL Consortium’s current specification is 4.0. Later revisions describe pooling, where a rack shares one large bank of memory and hands it to whichever server needs it, so capacity stops being stranded inside boxes that are not using it.
Why this is a purchasing question, not a spec-sheet question
We track memory prices every day because we quote servers every day. Measured as the best street price per gigabyte across the major memory lines, March 2026 to September 2026:
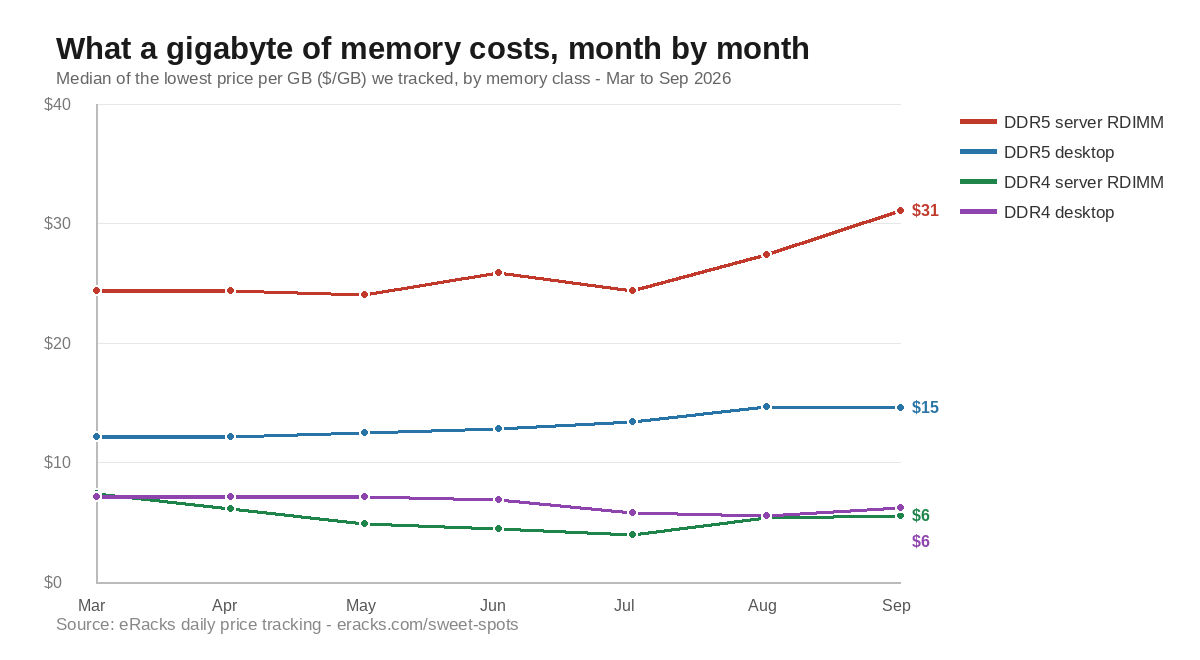
- DDR5 server memory (ECC RDIMM): $24.37 to $31.05 per GB, up 27 percent; the best available price went from $14.17 to $26.75, up 89 percent.
- DDR5 desktop memory: $12.19 to $14.58 per GB, up 20 percent.
- DDR4 server memory (ECC RDIMM): $7.44 to $5.56 per GB, down 25 percent.
- DDR4 desktop memory: $7.19 to $6.22 per GB, down 13 percent.
Two things follow. First, the memory you did not buy in March costs a third more today, and the cheap end of the market has closed up. Second, the previous generation is being liquidated: DDR4 server memory now costs a seventh of DDR5 per gigabyte. For a file server, a backup target, or a build server, where capacity matters and bandwidth does not, a DDR4 platform with its slots filled is the best value on the table this year.
In a sealed design none of this is available to you. You pay the day-one price for the day-one capacity, and a shortage or a glut in the memory market changes nothing about the machine you own. In a slotted design, or a fabric design, the market is your friend as often as your enemy: you buy the slots now, you fill them when the price is right.
What we do about it
Every quote we write shows the board’s slot count next to what the configuration fills, so the upgrade path is visible before the order rather than discovered after it. Some customers max the memory on day one, which is the right call for a machine with a known job; the AMD EPYC 9005 boards we build on carry 24 DIMM slots and up to 6TB, so there is usually room either way. The memory line in every quote is priced at that day’s street price from the same tracking above, so a customer who asks for 256GB today and 512GB in six months pays the market twice, not our guess once. And as CXL memory expanders reach the channel, they are quotable on the EPYC 9005 and Xeon 6 platforms as a third way to add capacity without touching a socket.
Sealed memory is the right design for an accelerator, where bandwidth is the whole point. For everything else, we would rather sell you the slots.
Prices are our own daily tracking of the lowest street price per gigabyte for each major memory line at Newegg, taken as the median across lines in each class; March 2026 versus September 2026.
joe September 17th, 2026
Posted In: News, servers, Technology
Tags: CAMM2, CXL, DDR4, DDR5, ECC RDIMM, EPYC 9005, HBM, memory price tracking, server memory prices, upgradeability
The April 2026 AI GPU Landscape: From $349 to $16,500, Which VRAM Fits Your Model?
Last updated April 2026. Prices move weekly — keep checking back.
If you’ve been watching the AI GPU market, you already know the usual tension: NVIDIA dominates mindshare and most of the benchmarks, AMD is cheaper per gigabyte of VRAM but software support lags, and Intel keeps quietly shipping cards that punch well above their price tag but nobody talks about them. Meanwhile the actual hardware question most customers ask us is just: “How much VRAM do I need, and what’s the cheapest card that gets me there?”
This post is our answer as of mid-April 2026. We’ve broken the market into seven VRAM tiers, from the $349 low-profile starter card to a $16,500 datacenter accelerator, and matched each tier to the model sizes it actually runs well. All prices are current street prices, not MSRPs. At the end we’ll tie each tier back to one of our AI servers.
What “VRAM fits my model” actually means
As a rule of thumb for local inference:
- Model weight size ≈ parameters × bytes per weight. A 7B-parameter model at 4-bit quantization needs roughly 3.5–4 GB. The same model in full FP16 precision needs ~14 GB.
- Add 2–4 GB of working memory on top for KV cache, context window, and runtime overhead — more if you want long contexts.
- If your model plus overhead doesn’t fit, you’ll spill to system RAM or disk, and your tokens-per-second drops by an order of magnitude.
So the VRAM tier you need is driven by what you want to run, not by marketing tier names. Here’s how the 2026 market actually lines up.
The seven tiers
| Tier | VRAM | Price range | Models it runs comfortably | Example cards |
|---|---|---|---|---|
| Low-Profile (2U) | 8–16 GB | $320–$450 | 3B–8B quantized, embeddings, small classifiers | RTX 5060 LP, Intel Arc Pro B50, nVidia RTX A1000/A2000 LP |
| Entry | 16 GB | $480–$1,500 | 7B–13B full, 30B quantized | RTX 4060 Ti, RTX 5070 Ti, RTX 5080, AMD RX 9060 XT 16GB, AMD RX 9070 |
| Workstation | 20 GB single-slot | $1,280–$2,500 | 13B full, 34B quantized; quiet, ECC, space-efficient | nVidia RTX A4000 Ada (single-slot), AMD Radeon Pro W7800 32GB |
| Prosumer | 24–32 GB | $2,000–$3,740 | 34B full, 70B quantized | RTX 3090 Ti refurb, AMD RX 7900 XTX, RTX 5090 (availability-dependent) |
| Server | 48 GB | $1,299–$8,800 | 70B full, early 100B class | Intel Arc Pro B60 Dual 48GB, RTX 6000 Ada, NVIDIA L40S (passive), AMD Radeon Pro W7900 |
| Flagship | 96 GB | ~$9,680 | 70B full comfortably, 120B quantized, long-context everything | RTX PRO 6000 Blackwell 96GB ECC |
| Datacenter | 192 GB HBM3 | $15k+ (by quote) | Serious training + 405B-class inference | AMD Instinct MI300X |
The two surprise cards of 2026
If you only remember two things from this post, remember these:
Intel Arc Pro B50 ($399). A 16 GB low-profile card for under $400 didn’t exist twelve months ago. This card ships with both a standard and a low-profile bracket in a dual-slot form factor, slides into a 2U chassis without drama, and gets you enough VRAM for 7B-class models, embedding pipelines, and small classification workloads. As a starter card for a team dipping into local AI, nothing NVIDIA sells competes on $/GB at this form factor.
Intel Arc Pro B60 Dual 48GB ($1,299). This one is genuinely wild. Intel’s Project Battlematrix puts two Arc Pro B60 GPUs on a single PCIe card with 48 GB total VRAM — at roughly a fifth the price of an NVIDIA RTX 6000 Ada ($7,150) or a quarter the price of an L40S ($8,800). The software stack isn’t as mature as CUDA and your specific workload may or may not run well on Intel’s Battlematrix Linux drivers, but if your model runs, you’re getting 48 GB of VRAM for $1,299. For inference-bound 70B-quantized workloads where you don’t need peak training throughput, this is the best $/VRAM-GB in the market right now by a wide margin.
The AMD side
AMD’s RDNA 4 generation (RX 9060 XT, RX 9070, RX 9070 XT) turns out to be genuinely competitive for consumer-grade AI inference once you’re running on a framework that’s ROCm-aware — llama.cpp, Ollama, and vLLM all work. Performance-per-dollar on 16GB RDNA 4 cards is very close to the NVIDIA 50-series and sometimes ahead. For customers who don’t need CUDA and want to avoid NVIDIA’s pricing, this is a real path.
On the workstation side, AMD’s Radeon Pro W7800 (32 GB) and W7900 (48 GB) are direct replacements for NVIDIA’s RTX A5000/A6000 at roughly half the price, with ECC memory and workstation driver support. If you’re building a quiet single-user AI workstation, the W-series deserves a serious look.
At the top end, the AMD Instinct MI300X with 192 GB of HBM3 is the only single card that holds an entire 405B-class model in VRAM without any quantization tricks. It’s quote-only, it’s expensive, and the software story is still improving — but for the handful of customers for whom “does it fit” is more important than any other consideration, it’s currently the only game in town below $30k.
Which eRacks AI server for which tier?
We built our AI rackmount server line around this same VRAM-first thinking. Each model defaults to a different VRAM tier out of the box, and you can upgrade within the tier or jump tiers at configuration time:
- eRacks/AILSA — 2U, from $5,995. Default tier: Low-Profile. The “affordable starter” for teams trying local AI for the first time. Upgrade chassis to 3U-GPU or 4U-GPU if you want to move up to full-height cards later.
- eRacks/AIDAN — 2U full-height (up to 3 GPUs mounted sideways), from $9,995. Default tier: Entry 16GB. For 7B–13B models full-precision.
- eRacks/AINSLEY — 4U, from $14,995. Default tier: Prosumer 24–32GB. For 34B full or 70B quantized, with room for up to 4 full-height GPUs.
- eRacks/AISHA — 4U 8-GPU, from $19,995. Default tier: Workstation. Scales to the Server and Flagship tiers with up to 8 full-height GPUs — including the Intel Arc Pro B60 Dual for 48GB-per-card pricing unavailable anywhere else.
All four run Ubuntu Linux LTS Server out of the box, come with ECC-capable DDR5 RAM up to 512 GB, and ship with assembly, burn-in, and a 3-year warranty.
A note about prices
Our internal component costs tracked above — and therefore the baseline configuration prices you see on each product page — are mid-April 2026. The two forces moving them right now are (1) the AI-driven DDR5 memory supply crunch, which has roughly doubled ECC server RAM pricing since Q3 2025, and (2) the NAND flash shortage pushing SSD prices up. We’ll keep this post synced with our configurator. If you see a number here that doesn’t match what the configurator shows, trust the configurator — it’s the system of record.
Questions we haven’t answered yet
This post is the overview. Over the next few weeks we’ll be publishing deeper dives on:
- Why we just bumped our RAM prices 3x — an honest look at the 2026 memory market
- Arc Pro B60 Dual vs RTX 6000 Ada — real-world benchmarks on Llama 3 70B quantized
- The eRacks AI server lineup in depth — AILSA, AIDAN, AINSLEY, AISHA side-by-side
Got a specific model you want to run and aren’t sure which tier fits? Drop us a line and we’ll build the configuration for you.
joe April 15th, 2026
Posted In: AI, Deep Learning, LLM, Local AI, New products, Open Source, Rackmount Servers, servers, Technology
Tags: AI, AMD Radeon, Blackwell, Deep Learning, eRacks, GPU, Inference, Intel Arc, Llama, LLM, Local AI, Machine Learning, Open Source, Rackmount Servers, RDNA 4, VRAM
Introducing the eRacks AI Server Lineup: RAM-First Local AI for the Real World
You Want Local AI
Tired of cloud AI bills that keep climbing? Worried about sending sensitive data to third parties? Want to run the latest open-source LLMs like DeepSeek, Llama, Mixtral, or Qwen — on your own hardware?
We’ve been getting a lot of questions about AI servers lately, so we’re excited to officially announce our RAM-optimized AI Rackmount Server lineup — four models designed from the ground up for local-first AI computing.
The Big Idea: RAM > GPU Hype
Here’s something the big vendors don’t want you to know: for many AI workloads — especially LLM inference, RAG pipelines, and vector search — total system RAM matters more than having the flashiest GPU.
Why? Because large language models need to fit somewhere. If your model doesn’t fit in VRAM, it spills into system RAM. If it doesn’t fit there, you’re swapping to disk — and that’s game over for performance.
Our servers are built around this insight. We focus on massive RAM capacity combined with COTS (Commercial Off-The-Shelf) GPUs — the cards you can actually buy, at prices that won’t require board approval.
Meet the Family
So far, we’ve got four models, each named after Celtic / Gaelic names that happen to start with “AI” (we couldn’t resist):
Model Form Factor Max RAM GPUs Starting Price Sweet Spot
eRacks/AILSA 2U 512GB Up to 3 (LP) $4,995 SMBs, solo devs, 200-600B+ models
eRacks/AIDAN 2U 3TB Up to 3 $9,995 Small teams, 800B+ models, RAG
eRacks/AINSLEY 4U 2TB Up to 4 $14,995 R&D, training, fine-tuning
eRacks/AISHA 4U 6TB Up to 8 $19,995 Enterprise, hosting, all MoE models
eRacks/AILSA — The Entry Point
“Affordable Innovative Local Server for Artificial Intelligence” 😄
AILSA is our compact 2U starter — perfect for startups, researchers, and developers who want local AI without the sticker shock. With up to 512GB RAM and 3 low-profile GPUs (Intel Arc B50 or NVIDIA RTX 5060 LP), it punches well above its weight class for inference workloads.
Best for: Private chatbots, development sandboxes, entry-level RAG, running 600B+ parameter models locally.
eRacks/AIDAN — “The RAMstack”
AIDAN steps up to Dual AMD EPYC processors and up to 3TB of DDR5 ECC RAM. This is the machine for teams doing serious vector search, RAG pipelines, or serving LLMs to multiple users.
Best for: Small-to-medium teams, 800B+ models, retrieval-augmented generation, production inference.
eRacks/AINSLEY — The R&D Workhorse
Our 4U Threadripper-based system with up to 4 full-size GPUs and 2TB RAM. AINSLEY is built for the folks who need to train, fine-tune, and experiment — not just run inference.
Best for: Research labs, AI/ML startups, fine-tuning on private datasets, local experimentation.
eRacks/AISHA — The Beast
“Advanced Intelligent Server for High-RAM AI”
When you need to go all-in: up to 6TB RAM, up to 8 GPUs, and dual Intel Xeon or AMD EPYC processors. AISHA handles the largest MoE (Mixture of Experts) models, multi-tenant deployments, and enterprise-scale AI infrastructure.
Best for: Enterprise hosting, 800B+ models, multi-user deployments, running every MoE model out there.
Why Local? Why Now?
A few reasons we’re seeing massive demand for on-prem AI:
Privacy — Your data never leaves your building
Cost control — No per-token fees, no surprise bills
No rate limits — Run as many queries as your hardware can handle
Model freedom — Run any open-source model: Llama, DeepSeek, Mistral, Qwen, Gemma, and more
Customization — Fine-tune on your own data without uploading it anywhere
100% Open Source Ready
All our AI servers ship with Ubuntu and Ollama pre-installed, plus your choice of models (Llama, DeepSeek, Qwen, etc.). We also support custom preconfigurations:
• PyTorch, TensorFlow, JAX
• Hugging Face Transformers
• LangChain, vLLM, LM Studio
• OpenWebUI, LibreChat
• Milvus, Chroma (vector databases)
• Docker / Podman for containerized workflows
And of course — Rocky Linux, Fedora, Debian, or whatever distro you prefer. It’s your hardware.
COTS GPUs: No Vendor Lock-In
We spec readily available GPUs — NVIDIA RTX 30×0/40×0/50×0 series, professional A-series cards, Intel Arc, and AMD options. No waiting 6 months for an allocation. No $30k price tags for a single card. Swap, upgrade, or scale on your terms.
Ready to own your AI stack?
👉 Check out the full AI Server lineup – eracks.com/products/ai-rackmount-servers/
👉 Contact us for a custom quote
We’re happy to help you figure out the right balance of RAM, GPU, and storage for your specific workloads. That’s what we do.
Get Started: eRacks.com/contact
j
joe January 17th, 2026
Posted In: AI, Deep Learning, LLM, Local AI, Ollama, Open Source, Rackmount Servers, RAG, Technology
Tags: AI, Deep Learning, DeepSeek, EPYC, eRacks, eRacks Partner, GPU, Llama, LLM, Local AI, Machine Learning, Ollama, Open Source, Rackmount Servers, RAG, Threadripper
Latest OSes
Mint 22.2 “Zara”, 22.1 “Xia”, Debian 13.0, 13.1, Fedora 42, and more now available
admin October 23rd, 2025
Posted In: Debian, Fedora, Linux, Mint, NEW, News, Open Source, Operating Systems, Technology
Tags: Debian, fedora, Latest OS, linux, Mint, Open Source, ubuntu
Debian 12.9, Mint 22.1, Fedora 41, more
As always, the latest releases are available to be installed, such as Linux Mint 22.1 (and of course 22.0), Debian Stable 12.9, of course Ubuntu LTS 24.04.1 (and 24.10), Fedora 41, Centos 10, and more – ask us for your favorite if you don’t see it listed.
J
joe January 28th, 2025
Posted In: Debian, Fedora, Linux, Mint, Open Source, Operating Systems, Technology