eRacks Systems Tech Blog
Open Source Experts Since 1999
Refurbished, Renewed, and Burned In: What We Do to a Used GPU Before It Ships
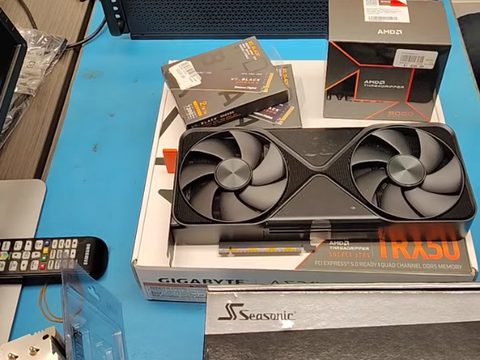
This week a customer’s IT team asked us for “more details on your refurb process”. One of them had already asked an AI assistant, which summarized our process from our own website: a 72-hour burn-in, fans checked, thermal pads refreshed. It got most of it right. Here is the full answer, from us.
Why refurbished at all
Our new systems ship with new parts, bought through authorized US distribution and validated-new sources, and that stays the default. Some customers ask for something else on purpose. The AMD Threadripper 3000 series is a good platform that distributors no longer carry. The GeForce RTX 3090 is the last GeForce card with NVLink (NVIDIA’s bridge that links two cards’ memory), which matters for some training work, and a pair of them costs a fraction of a current professional card. For builds like these the parts can only come refurbished or renewed, and we are glad to build them.
The words cover a lot of ground, though. “Refurbished” can mean a part that was properly reworked, or a used part that was wiped down and relisted. Our components page describes the other end of that market: “clean pull” lots with a short broker warranty, and server CPUs locked to their first owner’s firmware. We don’t buy from that market. Our refurbished cards come from refurbishers who back them with a warranty, and then every refurbished part goes through our own process.
What we do to a refurbished part
- Inspection. Every part is checked when it arrives, and anything that doesn’t meet our standards goes back. Not every “refurbished” or “renewed” part passes; we have rejected and returned some.
- Rework on the cards. We check the fans and replace them as needed, and we always replace the thermal compound or pads (the material that carries heat from the chip to the cooler). Worn connectors, plugs or jacks get replaced, and visibly marginal solder joints get resoldered. Then the card is cleaned and reassembled.
- Assembly. Everything is double- and triple-checked, neat, clean and properly cabled, and every card has to be recognized by its driver before we go further.
- Operating system and test suite. The OS and drivers go on, with our own utilities and our testing and burn-in suite.
- Burn-in. 72 hours of testing under full load, CPU, memory and every GPU together, including overnight runs and several multi-hour burn-ins, with temperatures logged and the driver logs watched for errors. If a part fails, we replace it and restart the burn-in from zero.
- The AI stack. On an AI server the stack goes on last, and the system is benchmarked with real models and tested before it ships.
The 72 hours are the same burn-in every eRacks system gets. The 24-hour minimum on our components page is typically for rush orders.
What it means for you
When a quote includes a refurbished or renewed part, it says so, line by line. Refurbished GPUs carry a 1-year warranty. And the system they go into gets the same assembly, the same checks and the same 72-hour burn-in as a system built entirely from new parts.
Looking at a previous-generation build, a pair of NVLinked cards, or an AI server on a budget? Browse our AI rackmount servers, or write to us at info@eracks.com and tell us what you need.
joe October 29th, 2026
Posted In: News, Technology
Tags: AI server, burn-in, eRacks, refurbished GPU, renewed hardware, RTX 3090, Threadripper
Introducing the eRacks AI Server Lineup: RAM-First Local AI for the Real World
You Want Local AI
Tired of cloud AI bills that keep climbing? Worried about sending sensitive data to third parties? Want to run the latest open-source LLMs like DeepSeek, Llama, Mixtral, or Qwen — on your own hardware?
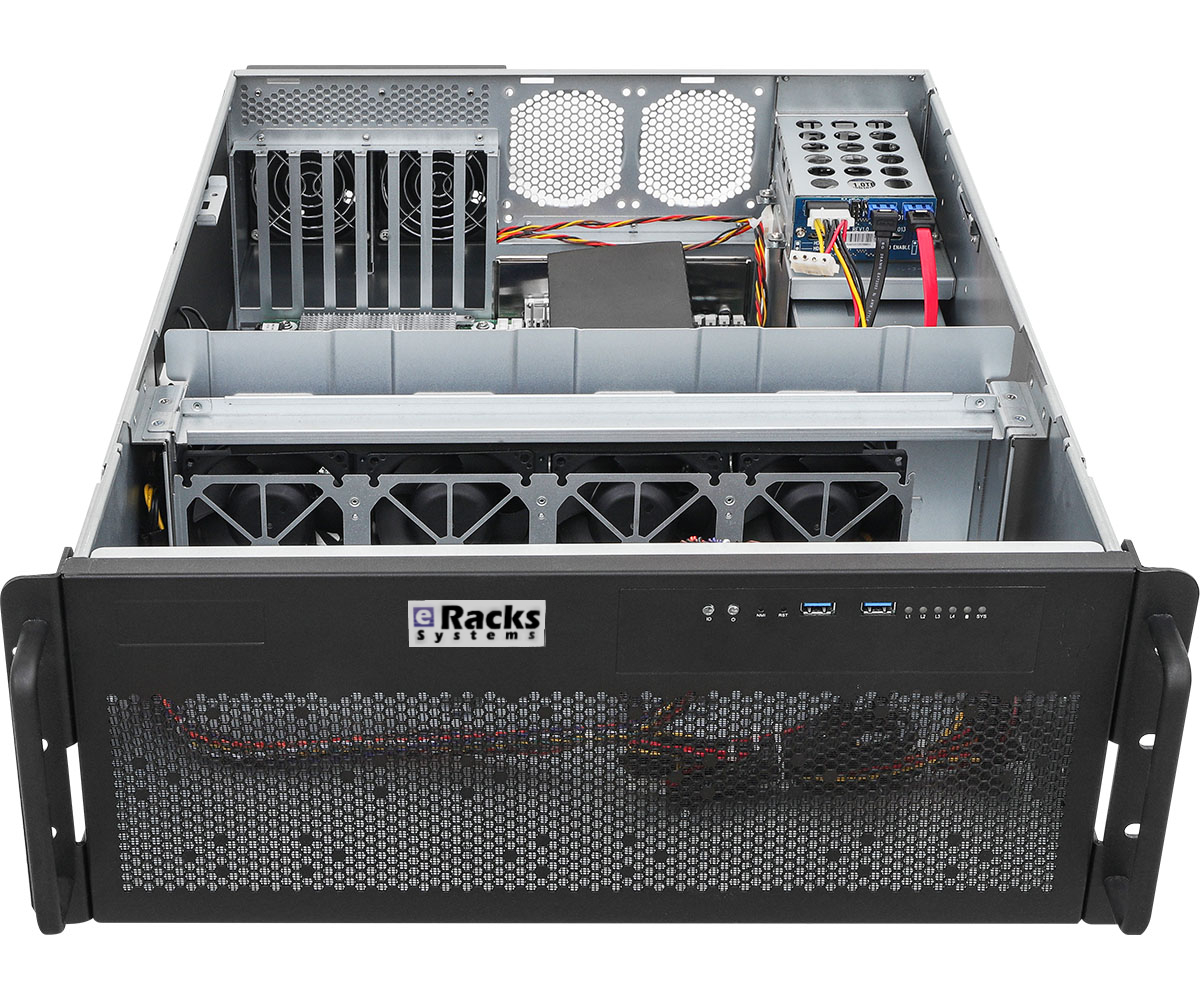
We’ve been getting a lot of questions about AI servers lately, so we’re excited to officially announce our RAM-optimized AI Rackmount Server lineup — four models designed from the ground up for local-first AI computing.
The Big Idea: RAM > GPU Hype
Here’s something the big vendors don’t want you to know: for many AI workloads — especially LLM inference, RAG pipelines, and vector search — total system RAM matters more than having the flashiest GPU.
Why? Because large language models need to fit somewhere. If your model doesn’t fit in VRAM, it spills into system RAM. If it doesn’t fit there, you’re swapping to disk — and that’s game over for performance.
Our servers are built around this insight. We focus on massive RAM capacity combined with COTS (Commercial Off-The-Shelf) GPUs — the cards you can actually buy, at prices that won’t require board approval.
Meet the Family
So far, we’ve got four models, each named after Celtic / Gaelic names that happen to start with “AI” (we couldn’t resist):
Model Form Factor Max RAM GPUs Starting Price Sweet Spot
eRacks/AILSA 2U 512GB Up to 3 (LP) $4,995 SMBs, solo devs, 200-600B+ models
eRacks/AIDAN 2U 3TB Up to 3 $9,995 Small teams, 800B+ models, RAG
eRacks/AINSLEY 4U 2TB Up to 4 $14,995 R&D, training, fine-tuning
eRacks/AISHA 4U 6TB Up to 8 $19,995 Enterprise, hosting, all MoE models
eRacks/AILSA — The Entry Point
“Affordable Innovative Local Server for Artificial Intelligence” 😄
AILSA is our compact 2U starter — perfect for startups, researchers, and developers who want local AI without the sticker shock. With up to 512GB RAM and 3 low-profile GPUs (Intel Arc B50 or NVIDIA RTX 5060 LP), it punches well above its weight class for inference workloads.
Best for: Private chatbots, development sandboxes, entry-level RAG, running 600B+ parameter models locally.
eRacks/AIDAN — “The RAMstack”
AIDAN steps up to Dual AMD EPYC processors and up to 3TB of DDR5 ECC RAM. This is the machine for teams doing serious vector search, RAG pipelines, or serving LLMs to multiple users.
Best for: Small-to-medium teams, 800B+ models, retrieval-augmented generation, production inference.
eRacks/AINSLEY — The R&D Workhorse
Our 4U Threadripper-based system with up to 4 full-size GPUs and 2TB RAM. AINSLEY is built for the folks who need to train, fine-tune, and experiment — not just run inference.
Best for: Research labs, AI/ML startups, fine-tuning on private datasets, local experimentation.
eRacks/AISHA — The Beast
“Advanced Intelligent Server for High-RAM AI”
When you need to go all-in: up to 6TB RAM, up to 8 GPUs, and dual Intel Xeon or AMD EPYC processors. AISHA handles the largest MoE (Mixture of Experts) models, multi-tenant deployments, and enterprise-scale AI infrastructure.
Best for: Enterprise hosting, 800B+ models, multi-user deployments, running every MoE model out there.
Why Local? Why Now?
A few reasons we’re seeing massive demand for on-prem AI:
Privacy — Your data never leaves your building
Cost control — No per-token fees, no surprise bills
No rate limits — Run as many queries as your hardware can handle
Model freedom — Run any open-source model: Llama, DeepSeek, Mistral, Qwen, Gemma, and more
Customization — Fine-tune on your own data without uploading it anywhere
100% Open Source Ready
All our AI servers ship with Ubuntu and Ollama pre-installed, plus your choice of models (Llama, DeepSeek, Qwen, etc.). We also support custom preconfigurations:
• PyTorch, TensorFlow, JAX
• Hugging Face Transformers
• LangChain, vLLM, LM Studio
• OpenWebUI, LibreChat
• Milvus, Chroma (vector databases)
• Docker / Podman for containerized workflows
And of course — Rocky Linux, Fedora, Debian, or whatever distro you prefer. It’s your hardware.
COTS GPUs: No Vendor Lock-In
We spec readily available GPUs — NVIDIA RTX 30×0/40×0/50×0 series, professional A-series cards, Intel Arc, and AMD options. No waiting 6 months for an allocation. No $30k price tags for a single card. Swap, upgrade, or scale on your terms.
Ready to own your AI stack?
👉 Check out the full AI Server lineup – eracks.com/products/ai-rackmount-servers/
👉 Contact us for a custom quote
We’re happy to help you figure out the right balance of RAM, GPU, and storage for your specific workloads. That’s what we do.
Get Started: eRacks.com/contact
j
joe January 17th, 2026
Posted In: AI, Deep Learning, LLM, Local AI, Ollama, Open Source, Rackmount Servers, RAG, Technology
Tags: AI, Deep Learning, DeepSeek, EPYC, eRacks, eRacks Partner, GPU, Llama, LLM, Local AI, Machine Learning, Ollama, Open Source, Rackmount Servers, RAG, Threadripper